News
Backup for Linux servers and containers: covering the workloads Windows-centric tools forget
Linux hosts and Docker containers are usually the least documented machines in an MSP's fleet, and the ones Windows-centric backup tools quietly skip. This guide covers what a correct backup of Docker volumes, databases and `/etc` actually looks like, how to make it consistent, and why one agent across every OS is the simplest way to close the gap.
Most backup suites sold to MSPs were designed around Windows desktops and Windows Server. They do that job well. But the fleet an MSP actually runs today also contains Linux hosts: a Proxmox or Ubuntu box in a client's rack, a Docker host running three line-of-business apps, a PostgreSQL server nobody wants to touch, a Raspberry Pi doing building access. These are often the machines with the least documentation and the most irreplaceable state, and they are the ones a Windows-centric agent either skips, covers with a half-working port, or leaves to an ad-hoc rsync script someone wrote in 2019.
The gap is rarely a decision. It happens because the Linux side of the fleet is small, the backup vendor's Linux agent is an afterthought, and "we'll sort it out later" never gets a ticket. This article walks through the Linux workloads that most often go uncovered, what a correct backup of each one looks like, and why running the same backup agent across every operating system in the fleet is the simplest way to close the gap.
Docker volumes: the state is not in the container
A container image is disposable; it can be pulled again from a registry in a minute. What cannot be pulled again is the data the container wrote while it ran. On a typical Docker host that data lives in one of three places:
Named volumes under
/var/lib/docker/volumes/<name>/_data. This is where databases, Nextcloud, Gitea, Home Assistant and most self-hosted apps keep their state when the compose file saysvolumes: - appdata:/data.Bind mounts, where the compose file points at a host path such as
/srv/app/config. Easy to find, easy to forget when the path is unusual.The compose files and
.envfiles themselves, usually in a home directory or/opt. Without them you know what data you have but not how to run it.
A backup tool that only knows about "My Documents" and C:\Users sees none of this. A Linux-native file backup that includes /var/lib/docker/volumes, the bind-mount paths and the compose directory covers all three.
The second problem is consistency. A running database inside a container is writing to its volume while you read it. Copying the files mid-write gives you a volume that may not start, or starts with silent corruption. There are three workable approaches, in order of preference:
Dump from inside the container before the file backup runs:
docker exec db pg_dump -U app app > /srv/backup/app.sql, then back up the dump file. The volume can still be included as a second line of defence.Stop the container, back up, start it again, wrapped in a pre- and post-backup script. Fine for a nightly window on an app with a few users; not fine for anything customer-facing.
Snapshot the filesystem (LVM, ZFS or Btrfs) and back up from the snapshot. Crash-consistent rather than application-consistent, but far better than a live copy, and transparent to the container.
Whichever you choose, it should be driven by the backup tool's own pre-run hook, not by a separate cron entry that may or may not fire before the backup starts.
Databases: a file copy is not a backup
On Windows, a backup agent can call Volume Shadow Copy and let SQL Server's VSS writer put the database in a consistent state. Linux has no equivalent that works across every database engine, which is why Windows-first tools tend to either skip the problem or claim "application-aware" support that covers one or two engines. The reliable answer on Linux is older and simpler: ask the database to produce a consistent export, then back up the export.
Engine | Consistent export | Notes |
|---|---|---|
PostgreSQL |
| Runs against a live server; the dump is a single transaction snapshot. |
MySQL / MariaDB |
|
|
SQLite |
| Copying the |
MongoDB |
| Use |
Redis | Back up | Only if the Redis data actually matters; often it is a cache. |
Two details decide whether these dumps are useful on the day you need them. First, write the dump to a directory the backup job includes, and let the backup tool's deduplication handle the fact that most of the dump is identical to yesterday's. A nightly 20 GB pg_dump costs very little storage when only the changed blocks are uploaded; the deduplication article walks through the numbers. Second, keep the dump command in the backup job's pre-run script rather than in a separate cron entry, so a failed dump fails the backup visibly instead of leaving a stale file to be backed up again for months.
If you also want the raw data directory (/var/lib/postgresql, /var/lib/mysql) in the backup as a fallback, take it from a filesystem snapshot, never from the live path.
Configuration in /etc: the small files that make a server rebuildable
A Linux server's data is often a few hundred gigabytes. Its identity is a few megabytes, scattered across /etc, and it is the part nobody backs up because it looks like it belongs to the operating system. Rebuilding a host from a fresh install plus restored data is a two-hour job if you have the configuration and a two-day job if you are reconstructing it from memory and old tickets.
The usual suspects:
/etc/nginx,/etc/apache2,/etc/haproxy— virtual hosts, redirects, upstream definitions/etc/letsencrypt— certificates and the account keys that renew them/etc/ssh,/etc/sudoers.d,/etc/passwd,/etc/group— who can log in and what they can do/etc/systemd/system— custom units, timers and overrides that make the services start/etc/cron.d,/etc/crontab,/var/spool/cron— the scheduled jobs, including the ones that run other backups/etc/fstab,/etc/netplan,/etc/network,/etc/wireguard— storage mounts and network, including VPN keys/etc/docker/daemon.jsonand/etc/default/*— the settings that make the host behave the way it does/optand/usr/local— software installed outside the package manager, with its own config
Two additions make the restore side easier. Save the installed package list (dpkg --get-selections or rpm -qa) to a file in the backup set, so a rebuild can reinstall everything in one command. And back up /etc as a whole, excluding nothing; it is small, it compresses well, and the file you excluded is always the one you needed.
The pattern that works is a backup job on every Linux host that always includes /etc, /home, /root, /opt, /srv, /var/lib/docker/volumes and the database dump directory, with per-host additions. Define it once as a template and apply it to new hosts at enrolment rather than hoping each one gets a job written by hand.
Cron-driven consistency: order the steps, or the backup lies
The classic Linux backup is a cron entry at 02:00 running a dump script and another at 03:00 running the file copy. It works until the dump takes longer than an hour, or the dump fails and nobody notices, or someone moves the file copy to 02:30 for an unrelated reason. From then on, the backup contains yesterday's dump every day, and reports success every day.
The fix is to stop treating the dump and the backup as two jobs. One job, with explicit stages:
Pre-run script: dump the databases, flush application caches, stop any container that cannot be dumped, take the filesystem snapshot if you use one.
Backup: run against the dump directory and the snapshot path, not the live data.
Post-run script: restart what was stopped, remove the snapshot, delete dumps older than the local retention you want on disk.
Report: the job's status reflects every stage. A failed pre-run script fails the job.
The last point is the one that matters. A backup tool with proper hooks lets you mark the pre-run script as required, so a dump that exits non-zero aborts the run and raises an alert, instead of quietly backing up stale files. That one setting turns "we think the database is backed up" into something you can show an auditor.
A few habits that keep this reliable on Linux hosts:
Write scripts with
set -euo pipefailso a failing command inside the script is reported, not swallowed.Log to a file the backup includes, so the history of pre-run output travels with the backup.
Keep the scripts themselves under
/etcor/opt, so they are in the backup too.Use the backup tool's scheduler for the whole job rather than cron, so there is one place to see when it last ran and whether it finished.
The same structure covers Windows hosts, where the pre-run stage is usually a VSS snapshot instead of a dump. Which is the point of the next section.
Why cross-platform agents matter in a mixed fleet
An MSP with 40 clients does not have a Linux problem or a Windows problem; it has a fleet problem. A typical client has Windows workstations, one or two Windows servers, a Linux host or appliance, a couple of Macs in the design team, and a growing number of workloads that are really containers on a Linux VM. When the backup tool covers only part of that, one of three things happens:
A second tool. Now there are two consoles, two alerting paths, two retention policies, two things to explain in the quarterly review, and a technician who knows one but not the other.
A script. Usually rsync or a tarball to a NAS, written by whoever last touched the box. No encryption, no deduplication, no central status, and no owner once that person leaves.
Nothing. The Linux host is "on the list". It stays on the list until it fails.
A single agent that runs the same way on Windows, Linux and macOS, and inside a container, removes the decision. Every host gets enrolled the same way, gets a job from the same template, reports to the same console, and shows up in the same compliance report. The pre-run and post-run hooks described above are the same feature on every platform; only the script differs.
There is a practical restore benefit too. When a Linux host and a Windows host use the same backup format and the same storage, a technician can restore files from the Linux box to a Windows workstation to hand to a client, or rebuild a failed Linux appliance from a Windows laptop, without finding the one person who knows the Linux tool. The backup becomes portable because the agent is.
How Duplicati covers the whole fleet
Duplicati was built cross-platform from the start rather than ported later. The same agent runs on Windows, Linux (x64 and ARM, including Raspberry Pi and NAS devices), macOS, and as an official Docker image, and every one of them produces the same encrypted, deduplicated backup format to the same storage.
For the Linux workloads in this article, the relevant pieces are:
Pre- and post-run scripts on every job, with the option to make the pre-run script required, so a failed database dump fails the backup instead of hiding behind a green status.
Filesystem snapshots through LVM on Linux and VSS on Windows, selected per job, so live data directories are read from a consistent point in time.
Container-friendly packaging. Run Duplicati itself as a container on a Docker host with the volumes directory and compose paths bind-mounted into it, and it backs up every other container on the box the same way it would back up a bare-metal server.
Storage independence. Any S3-compatible bucket, Backblaze B2, Azure, Google Cloud, SFTP, WebDAV, a local NAS, or Duplicati Integrated Storage, with client-side encryption before anything leaves the host.
Block-level deduplication that makes nightly full database dumps cheap to keep for months, since only the changed blocks are uploaded.
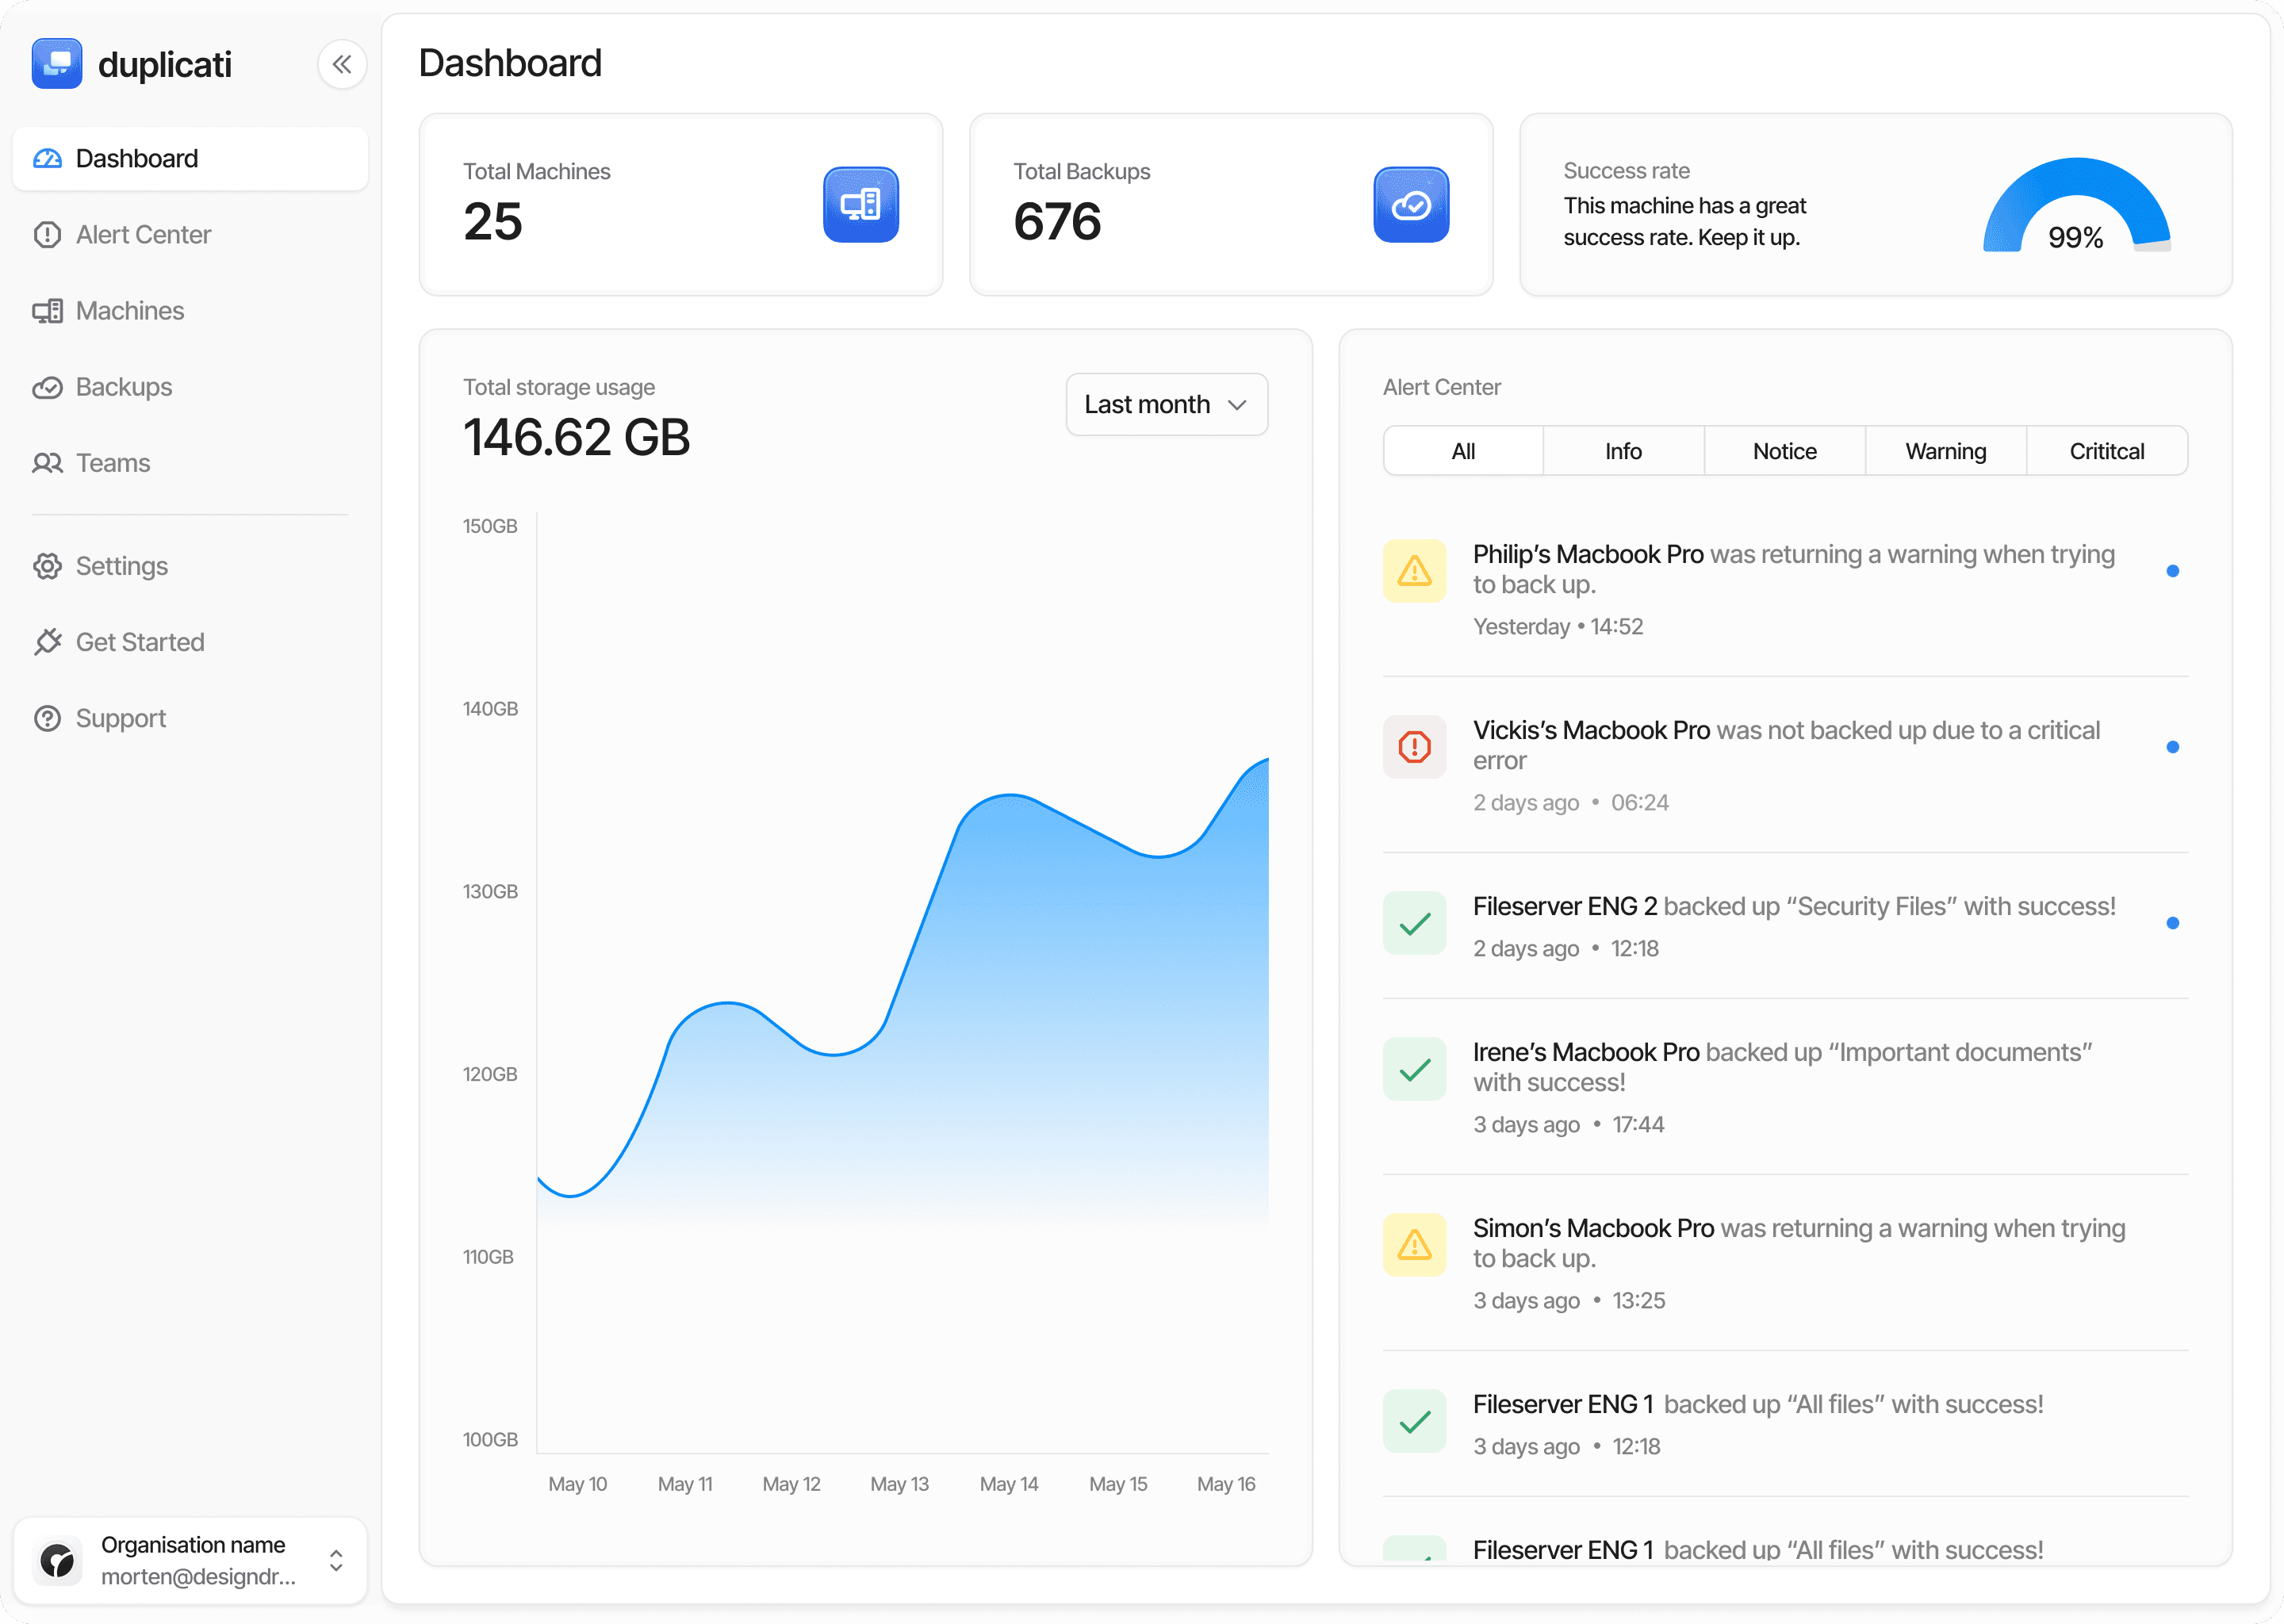
With the Duplicati Console, the Linux hosts stop being a separate workflow. Enroll a machine, apply a job template with the paths and scripts for its role, and it reports alongside the Windows fleet: last run, next run, warnings, and failures, in one view and one alert stream. Remote control lets a technician adjust a job or start a restore on a client's Linux box without a separate SSH session, and the compliance report covers every operating system in the same table.
For MSPs comparing suites, this is the concrete difference. Most MSP-focused backup products treat Linux as an add-on with a reduced feature set, and treat containers as out of scope. Duplicati treats them as hosts like any other.
A checklist for every Linux host in the fleet
Before you call a Linux server or Docker host covered, check that the backup job:
Includes
/etc,/home,/root,/opt,/srvand a saved package listIncludes
/var/lib/docker/volumes, every bind-mount path, and the compose and.envfilesDumps each database in a required pre-run script, and backs up the dump directory
Reads live data directories from a snapshot, never from the live path
Restarts anything the pre-run script stopped, in a post-run script
Fails visibly when any stage fails, and alerts the same channel as the Windows fleet
Reports to the same console, under the same retention and compliance policy, as every other host
Has been restored at least once to a different machine
The Linux side of a mixed fleet is small enough to be forgotten and important enough to hurt when it is. One agent, one template per role and one console make it ordinary, which is the whole goal.
Ready to put the Linux hosts under the same roof as the rest? Start a Duplicati Console trial and enroll your first Linux server in minutes.