News
How to Write a Backup SLA That MSPs Can Actually Keep
Most backup SLAs are written to win the deal, not to be kept — and the gap shows up on a Friday night when the restore takes 14 hours and the contract says nothing about weekends. This guide explains RPO and RTO in plain terms, what to promise for each tier of data, what you must monitor to prove you kept your word, and the clauses that end up in dispute.
Most backup SLAs are written to win the deal, not to be kept. They promise "daily backups" and "rapid recovery," numbers nobody measured, and a credit scheme nobody can calculate. Then a server dies on a Friday night, the restore takes 14 hours, and both sides discover the contract says nothing about weekends.
This article is the version you can keep. It covers what RPO and RTO actually mean, what to promise for each kind of data, what you must monitor to know you are meeting the promise, and the handful of clauses that end up in dispute. None of it is legal advice; take the structure to your lawyer, not the wording.
One principle runs through all of it: only promise what your tooling can prove. If you cannot produce a report that shows the number, do not put the number in the contract.
RPO and RTO in plain terms
RPO (Recovery Point Objective) is how much work the customer can afford to lose. If backups run every 24 hours, the RPO is 24 hours: a failure at 4 pm loses everything since last night. RPO is set by backup frequency, and nothing else.
RTO (Recovery Time Objective) is how long the customer can afford to be down. It is the clock from "we declare an incident" to "the data is usable again." RTO is set by where the data lives, how fast you can pull it back, how much of it there is, and who is available to do the work.
The two are independent. A customer can have a tight RPO and a loose RTO (hourly backups to cheap cold storage, restored over a day) or the reverse (nightly backups kept on a local appliance that restores in minutes). Pricing follows the same split: RPO costs you backup runs and storage churn, RTO costs you fast storage, standby hardware, and people on call.
Three things to get right when you write them down:
State RPO as a maximum, measured per backup set. "RPO: 4 hours" means the newest successful backup is never older than 4 hours. A failed run does not reset the clock; it blows the RPO.
Start the RTO clock at a defined event. Not "when the server failed" (nobody knows when that was) but when the customer reports it or your monitoring flags it, whichever is first, and only during covered hours unless you sell 24×7.
Define "recovered." For files it usually means the data is readable at the original path. For a server it means the service answers requests. Pick one per data type and write it down; most RTO disputes are about this word.
A fourth number is worth stating even though nobody asks for it: retention, how far back a restore can reach. A 7-day retention means a ransomware infection discovered on day 9 has no clean copy to go back to. Retention is where ransomware recovery lives, so treat it as part of the SLA, not a storage detail.
What to promise per data type
One RPO and one RTO for "the customer's data" is the most common mistake. A line-of-business database and a folder of marketing photos do not deserve the same promise, and pricing them the same means you either overcharge for the photos or lose money on the database. Sort the customer's data into three or four tiers, agree the tier list in the contract, and attach numbers to tiers rather than to systems.
The figures below are a defensible starting point for a typical SMB customer with file-level backup to cloud storage. Adjust them to what your tooling and your storage can actually deliver.
Tier | Typical contents | RPO (max data loss) | RTO (covered hours) | Retention | Restore test |
|---|---|---|---|---|---|
1 – Critical | Line-of-business databases, accounting, ERP, domain controllers | 1–4 h | 4–8 h | 90 days + monthly for 12 months | Quarterly |
2 – Important | File servers, shared drives, email archives, SharePoint/OneDrive | 12–24 h | 24 h | 90 days | Semi-annual |
3 – Standard | Workstations, departmental shares, project archives | 24 h | 48–72 h | 30–60 days | Annual |
4 – Archive | Cold data, old projects, completed-case files | 7 days or on change | 5 business days | 1–7 years as required | Annual, sample |
A few notes on the table:
Tier 1 RTO assumes the hardware exists. If the customer's only server has burned, 4 hours is impossible unless you also sell standby hardware or a cloud failover. Write the hardware assumption into the clause (see Disputes, below).
RTO should scale with volume above a threshold. A 20 TB file server cannot come back over a 100 Mbit line in 24 hours. State a base RTO up to a size (say 2 TB) and an added allowance per TB beyond it, or require a local copy for data sets above the threshold.
Retention is what makes the ransomware clause real. Tier 1 and 2 need enough depth that a dormant infection has a clean version to fall back to. 90 days plus monthly snapshots is a reasonable floor; the customer's regulator may set a higher one.
Restore tests are part of the promise, not a bonus. A backup that has never been restored is a hypothesis. Commit to a cadence per tier and to reporting the result, and price the time in.
Put the tier assignment in a schedule, not the body. Systems change. A schedule the customer initials can be updated with a short amendment; a tier buried in clause 7.3 requires a renegotiation.
SaaS data (Microsoft 365, Google Workspace) deserves its own line if you back it up. The platform's own retention is not a backup and should not be counted toward yours; say so explicitly so the customer does not assume Microsoft's recycle bin is covered by your SLA.
Monitoring obligations
An RPO you do not monitor is a number you will discover you missed when the customer calls. The SLA should say what you watch, how fast you react, and what the customer gets to see. This is the section that separates an MSP from a reseller: the customer is paying you to notice.
Commit to these, in writing:
Every backup job reports to a central console. Not email alerts to a shared inbox. A single view that shows, for every endpoint, when the last successful run finished and how large it was. If an agent stops reporting, that is itself an alert.
A missed-RPO alert within a defined window. If a Tier 1 set has no successful backup inside its RPO, someone is notified within, say, 1 hour of the breach, and a ticket is opened. State the window; "promptly" is not a window.
Failure triage within the next business day. A failed job gets a human looking at it and either fixed or escalated to the customer (for example, a locked file or an offline machine) within one business day. Two consecutive failures on a Tier 1 set escalates the same day.
A monthly report the customer actually receives. Per protected system: success rate, oldest successful backup, storage used, restore tests performed and their outcome, and any RPO breaches with cause. This is the evidence that you kept the SLA, and it is also the evidence in a dispute, so build it from the console's data rather than by hand.
Restore verification on the agreed cadence. Log each test with the date, what was restored, how long it took, and whether it matched. The restore time becomes your measured RTO; if it is creeping up, you know before the customer does.
And two things to put on the customer's side of the ledger:
They must keep the agent installed and the machine online for the backup window. A laptop that is closed every night is not an RPO breach on your part. Write in that a machine unreachable for the whole window is excluded from that period's measurement, and that you will report it as "not backed up" rather than silently drop it.
They must tell you about new systems. Anything not in the tier schedule is not covered, and the report should list unmanaged machines the console can see so the gap is visible to both sides.
The practical test for this section: could you hand a customer last month's report and a copy of the contract and let them check you kept it without asking you a single question? If not, either the monitoring or the contract needs changing.
The clauses that cause disputes
Backup SLA disputes almost never turn on the headline numbers. They turn on definitions that were left vague, exclusions nobody read, and remedies that were never calculated. Here are the ones that come up repeatedly, with how to close each.
"Recovered" means different things to each side. The MSP restores the files; the customer says the application still does not work. Fix: define recovery per tier. Tier 1: service responds and the customer's named contact confirms. Tier 2 and 3: data readable at the original or an agreed alternative location. Application reconfiguration beyond the restore is a separate service unless the contract says otherwise.
When the RTO clock starts. The customer says the server died at 02:00; your ticket was opened at 09:15. Fix: the clock starts at the earlier of your monitoring alert or the customer's ticket, and runs only during covered hours unless 24×7 is purchased. Say which time zone.
Hardware and connectivity are assumed, silently. You promised 8 hours; the replacement server arrived on day three. Fix: RTO is measured from the moment suitable target hardware and connectivity are available. Offer a priced option (standby hardware, cloud failover) that removes the assumption for customers who need it.
Scope creep in what is "backed up." A new VM appeared six months ago and was never added. Fix: coverage is the tier schedule, and only the tier schedule. Your monthly report lists visible but unmanaged systems; after that, the gap is a shared fact.
Ransomware and the "clean copy" argument. The customer wants the state from before the infection; your retention only reaches back three weeks and the infection is older. Fix: tie the ransomware promise to retention depth, state it in days, and make clear that a restore from an infected point is still a successful restore under the SLA. If the customer wants longer reach-back, that is a retention upgrade with a price.
Service credits that cannot be computed. "Reasonable compensation" is an invitation to argue. Fix: a fixed percentage of the monthly fee for the affected system, per breach, with a monthly cap (10–25% of that system's fee is common), claimed in writing within 30 days, and stated as the sole remedy for SLA breach. Keep data-loss liability in the master agreement, capped at fees paid over a defined period.
Exclusions that swallow the promise. Many SLAs exclude "circumstances beyond the provider's control," which can cover almost anything. Fix: list the exclusions. Customer-side outages, machines offline during the backup window, changes made without notice, third-party platform failures (with named platforms), and force majeure. Nothing else.
Termination and the last backup. The contract ends and the customer asks for their data, or asks you to keep it. Fix: state the hand-over format and timeline (for example, a full export in a documented format within 30 days), how long you retain after termination, and that storage during that period is billable.
Encryption keys. If the customer holds the key and loses it, the backup is unrecoverable and the SLA cannot be met. Fix: say whose keys they are, who keeps a copy, and that key loss by the customer voids the recovery promise for the affected data. This clause is short and prevents the worst conversation an MSP can have.
Price the tiers, not the terabytes
An SLA written this way does a second job: it is a pricing sheet. Each tier carries a cost you can name. Tier 1 costs backup runs every few hours, deep retention, quarterly restore drills and someone on call; Tier 4 costs almost nothing but storage. When the customer asks why the accounting server costs four times the file server, the tier table answers for you, and when they want a tighter RTO, the price of Standby Recovery is already on the page.
That is the pairing with the pricing framework we have written about before: charge per protected system per tier, keep storage as a line that rarely matters, and let the SLA define what the customer is buying. Customers who understand what each tier promises stop shopping on price per gigabyte.
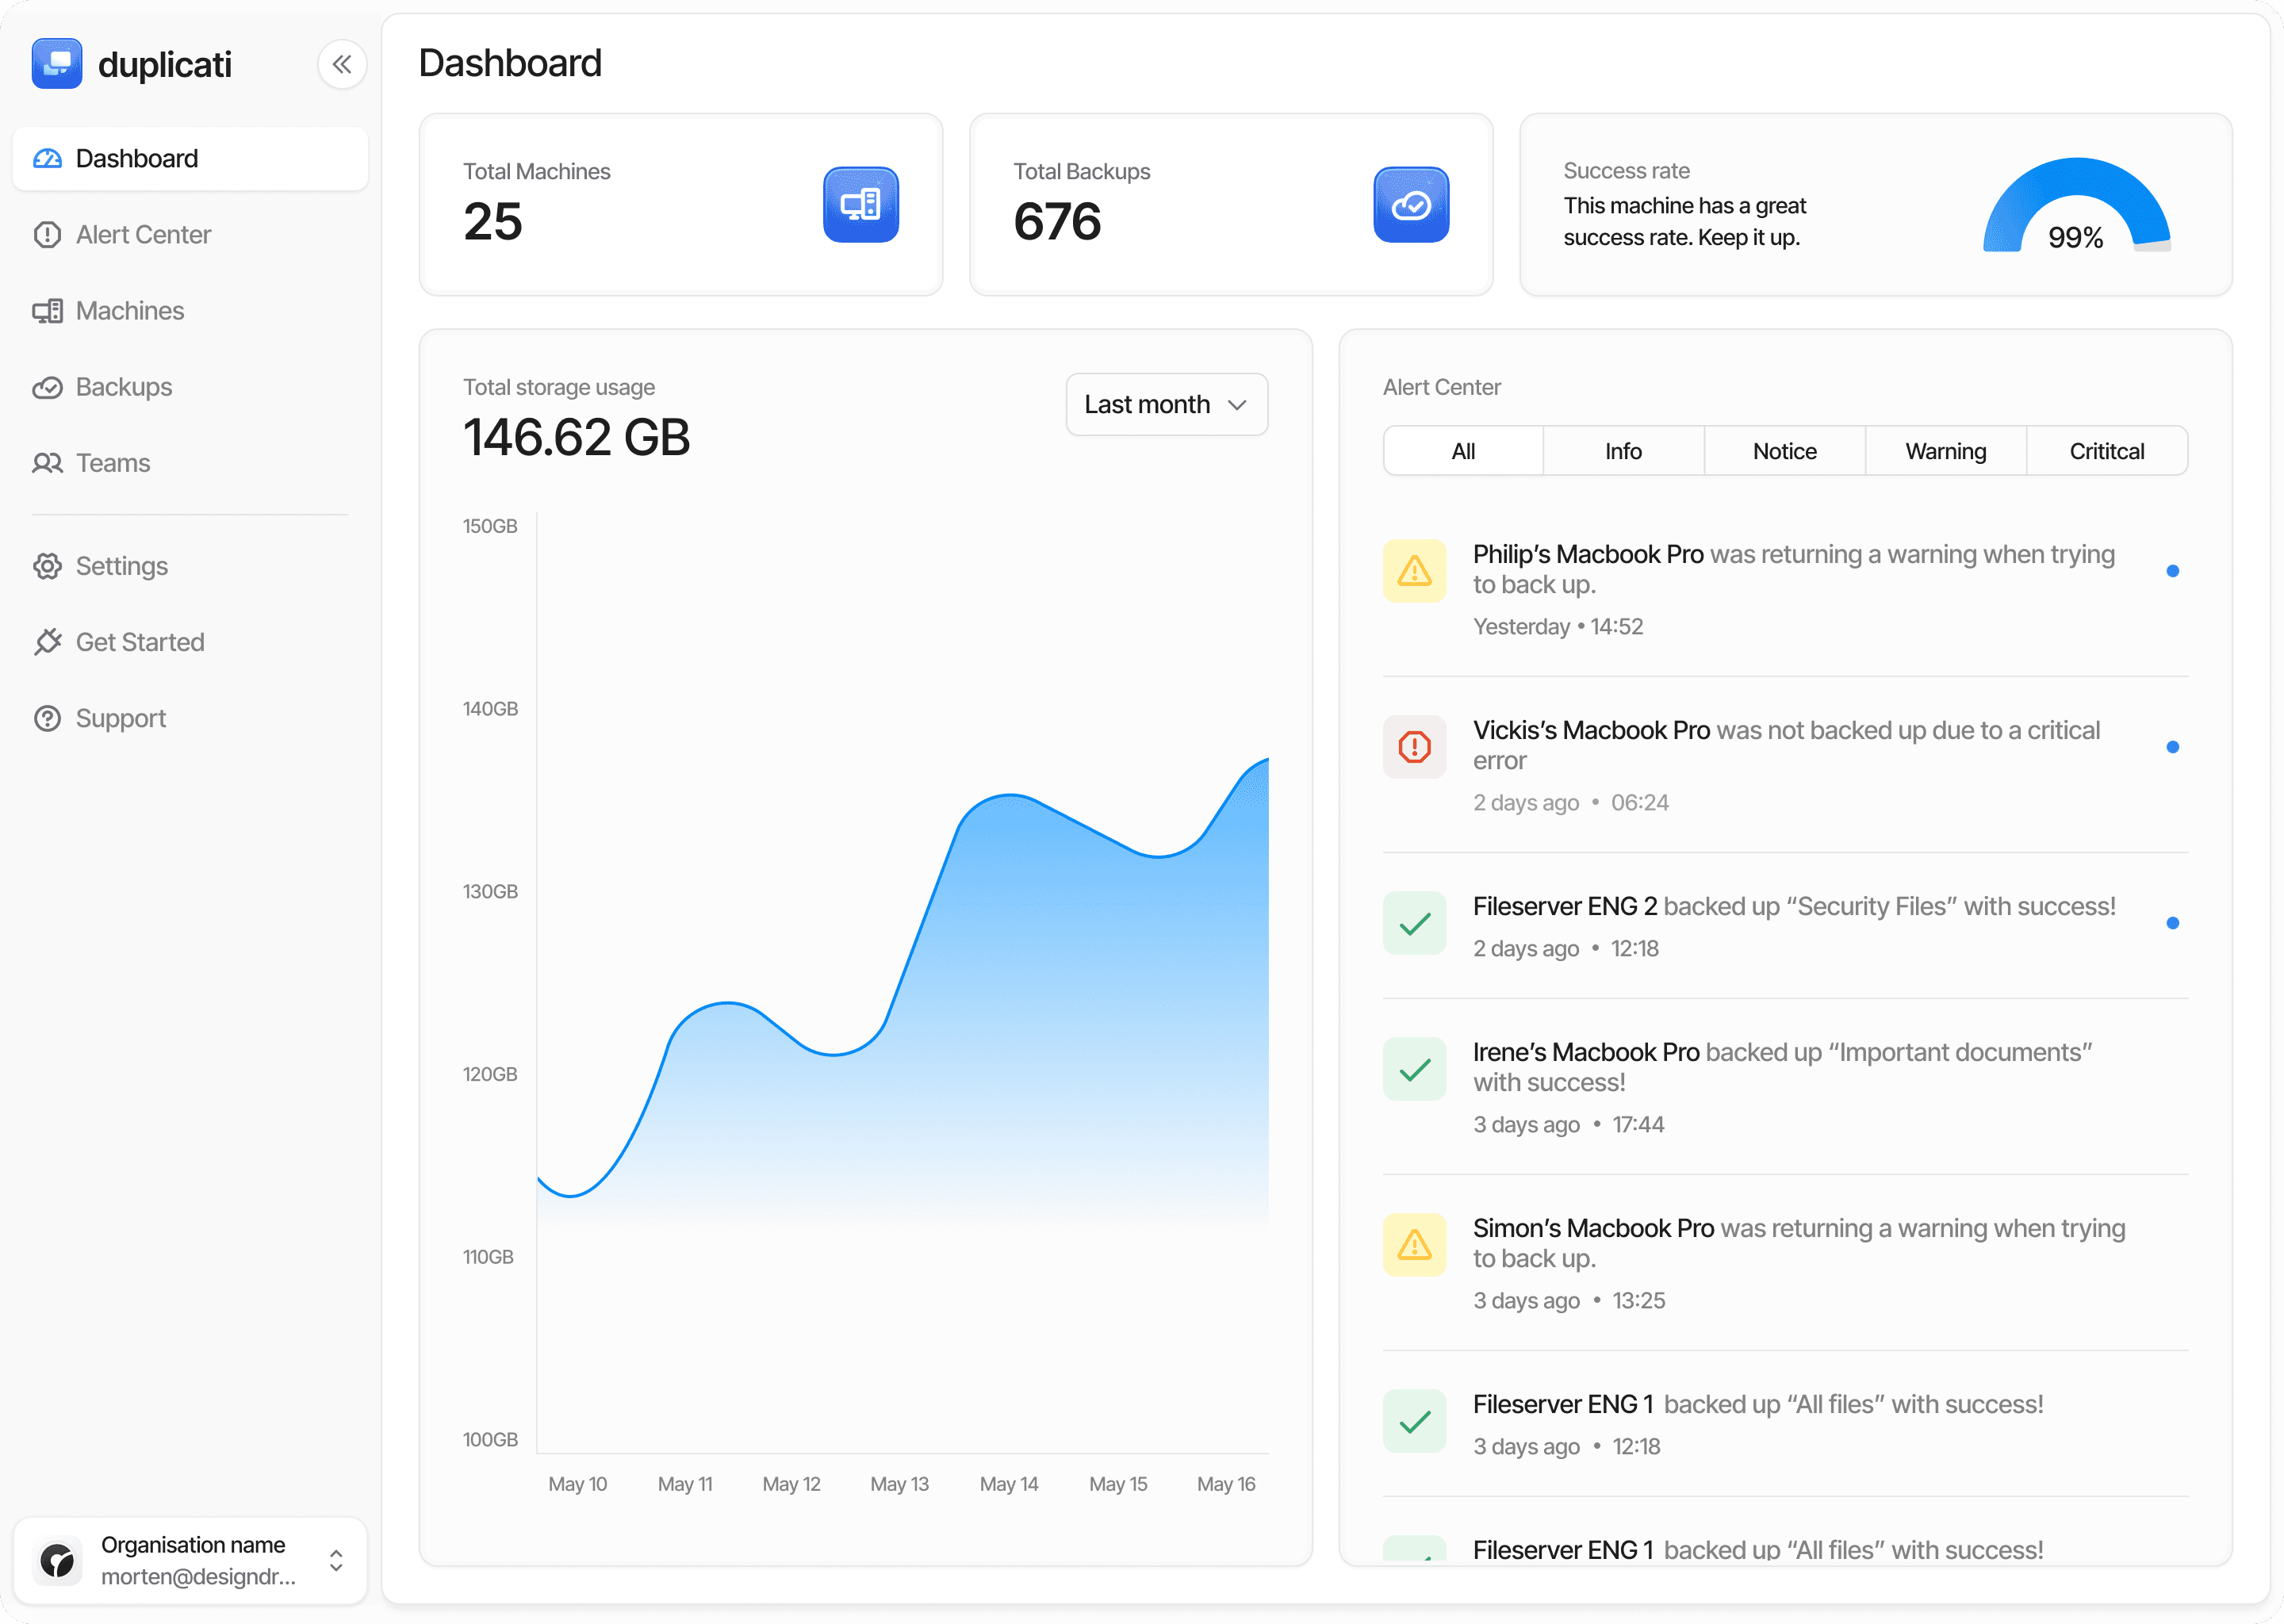
None of it works without the monitoring obligations above. The monthly report is the SLA; everything else is a promise. Duplicati Console was built for exactly this: every backup job, across every customer, reporting into one view with the age of the last good backup, the storage used, and the failures that need a person, so the report you owe the customer is a query rather than a chore. If you are writing or rewriting your backup SLA, check each promise against what your console can prove today.